NVIDIA H100 NVL 94GB HBM3 Tensor Core GPU 900-21010-0020-000: Hopper Acceleration Built for Large Language Models
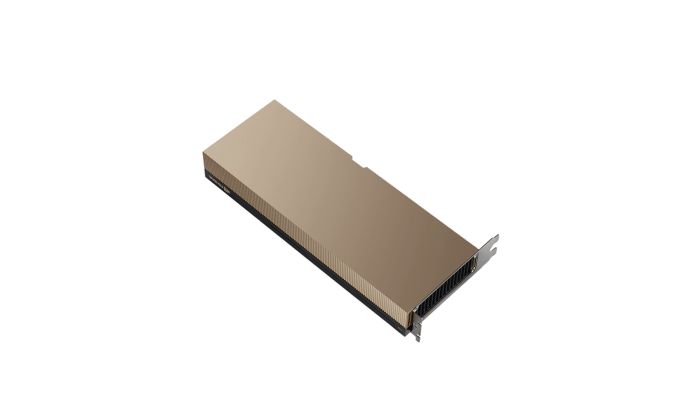
The NVIDIA® H100 NVL Tensor Core GPU is purpose-built to accelerate large language model (LLM) inference and the most demanding generative AI and high-performance computing (HPC) workloads. Based on the NVIDIA Hopper™ architecture, the H100 NVL pairs two NVLink-bridged PCIe cards - each with 94GB of high-bandwidth HBM3 memory - to deliver the memory capacity and bandwidth that today's largest transformer models require.
Key Features and Benefits of the NVIDIA H100 NVL 94GB Tensor Core GPU
Optimized for Large Language Model Inference
The H100 NVL is tuned for GPT-class large language models. Its fourth-generation Tensor Cores and dedicated Transformer Engine with FP8 precision dramatically accelerate transformer inference, while 16,896 CUDA cores and 528 Tensor Cores per GPU provide massive parallel throughput.
Exceptional Memory Capacity and Bandwidth
Each H100 NVL GPU delivers 94GB of HBM3 memory with approximately 3.9 TB/s of memory bandwidth - among the highest available - so large models fit in memory and run with minimal data movement. Across the NVLink-bonded pair, 188GB of combined HBM3 keeps even very large models resident for low-latency inference.
High-Speed NVLink and PCIe Gen5 Connectivity
The two cards are joined by NVIDIA NVLink® bridges for high-bandwidth, low-latency GPU-to-GPU communication, and each connects to the host over PCIe Gen5 x16 at 128 GB/s. This design scales performance for large models that exceed the memory of a single GPU.
Multi-Instance GPU (MIG) Flexibility
Multi-Instance GPU technology partitions each H100 NVL GPU into as many as seven fully isolated instances, enabling secure, right-sized acceleration and maximum utilization across concurrent workloads.
Energy Efficiency and Thermal Management
Each passively cooled, dual-slot full-height, full-length card is designed for standard PCIe Gen5 servers and operates within a configurable thermal design power envelope, relying on system airflow for efficient cooling in dense deployments.
Enterprise-Ready Software and Reliability
The H100 NVL includes NVIDIA AI Enterprise support and features ECC memory, Secure Boot, and hardware-isolated MIG instances for data integrity and secure multi-tenant operation in production AI environments.
Deploy the NVIDIA H100 NVL 94GB HBM3 Tensor Core GPU 900-21010-0020-000 to power the next generation of large language model and generative AI infrastructure.
Compute Performance
Acceleration Applications: Large Language Model Inference, Generative AI, Deep Learning, and HPC. Figures are per GPU.
| FP8 Tensor Core | 3,958 TFLOPS* |
|---|---|
| FP16 Tensor Core | 1,979 TFLOPS* |
| TF32 Tensor Core | 989 TFLOPS* |
| FP64 Tensor Core | 67 TFLOPS |
| INT8 Tensor Core | 3,958 TOPS* |
Features & Capabilities
Software: NVIDIA AI Enterprise. Multi-Instance GPU: up to 7 fully isolated instances per GPU. Ships as a 2-GPU NVLink-bridged pair.
| Memory (per GPU) | 94GB HBM3 |
|---|---|
| Memory Bandwidth (per GPU) | 3.9 TB/s |
| Interconnect | PCIe Gen5 128 GB/s; NVLink 600 GB/s |
| Form Factor | FHFL Dual-Slot, 2-GPU NVLink pair |
| Thermal Solution | Passive |
* Peak theoretical performance shown with sparsity; approximately one-half without sparsity.