






By Enterasource Posted on October 7, 2026
Read More
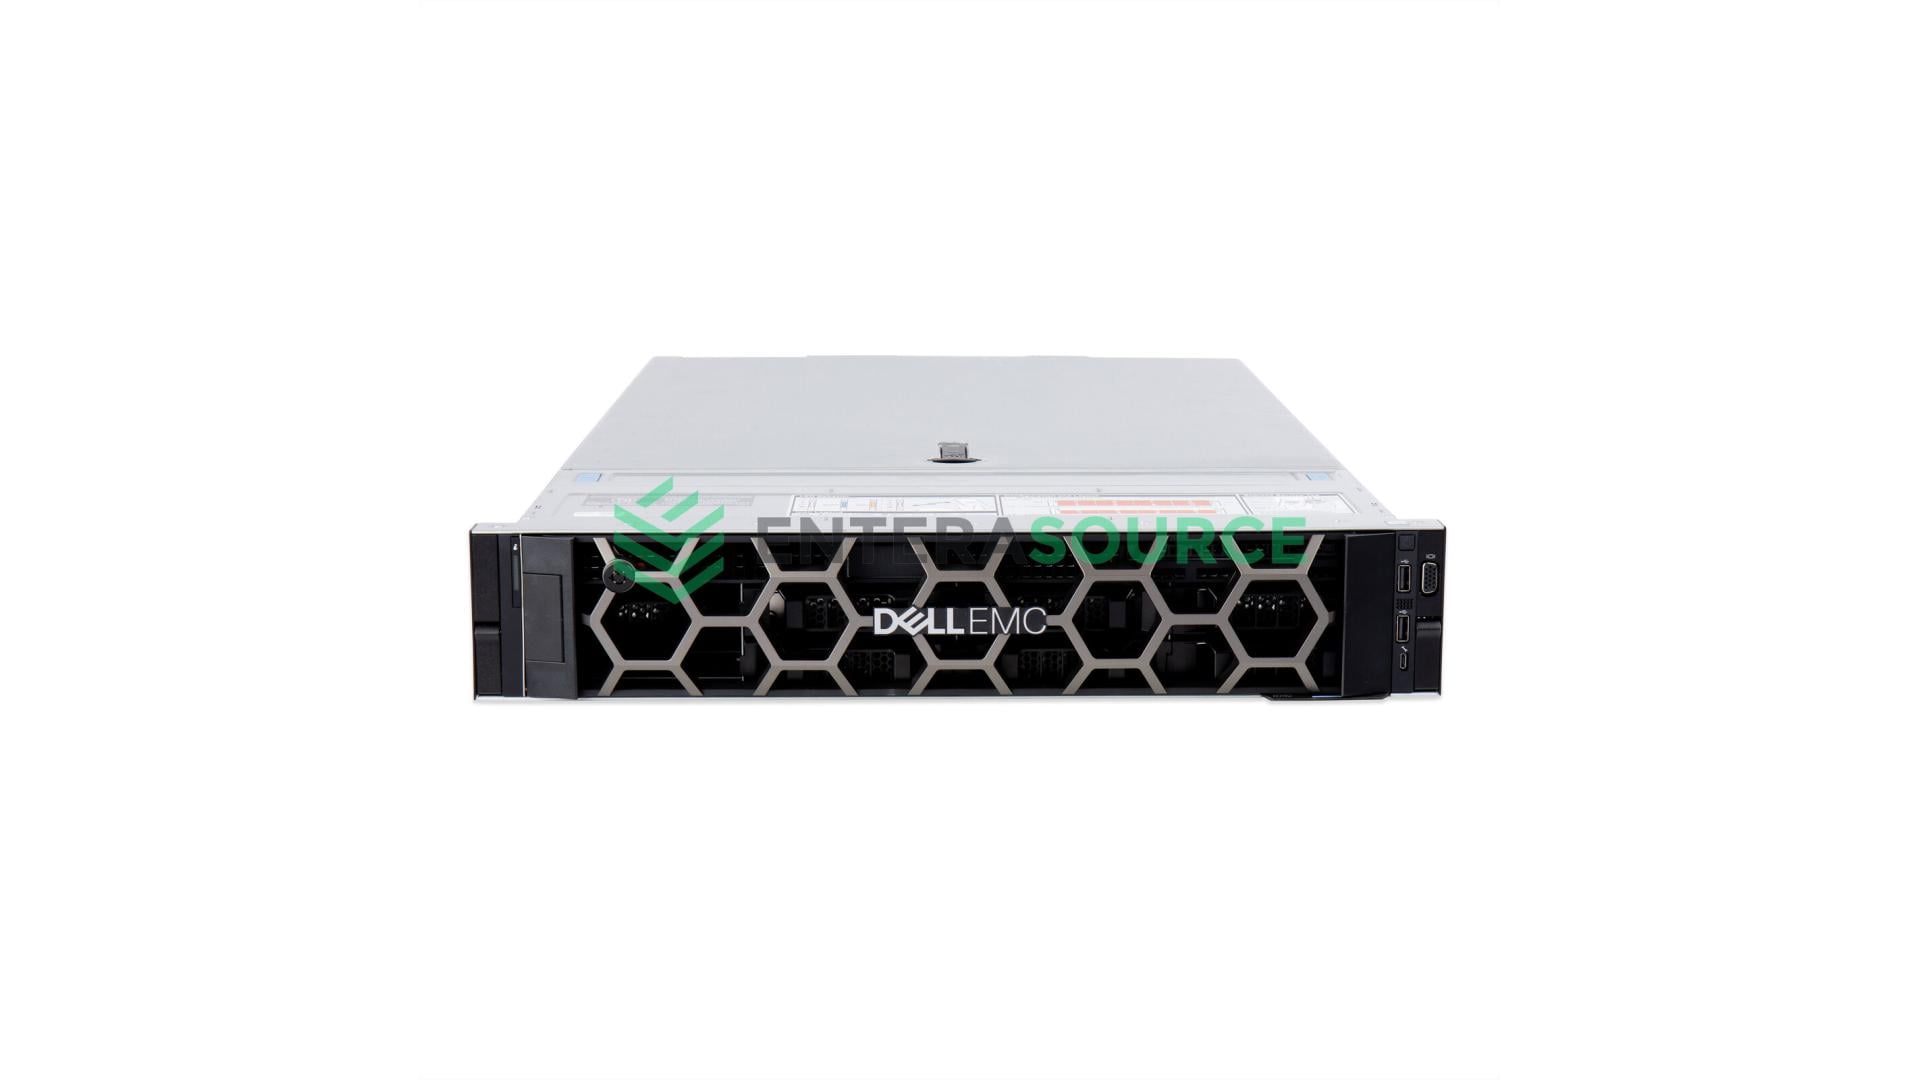
On-Prem LLM Hardware: How to Size GPU Servers When You Move Off Cloud AI APIs
How to size on-prem LLM hardware when you move off a cloud AI API: GPU memory for weights and KV cache, GPU and server choice, MLPerf throughput, power and cooling, and a break-even formula without prices.